In Asana’s September survey, 68% of CIOs and AI leaders said they use three or more AI agents in a typical week. Among office workers it was 36%, and every one of those workers already uses AI. CIO Dive reported it under the headline “Agentic AI gap persists between executives, workers“. Asana’s own explanation is about coordination and trust: workers have more tools to juggle and more outputs to reconcile, and they trust agents less than their leaders do.
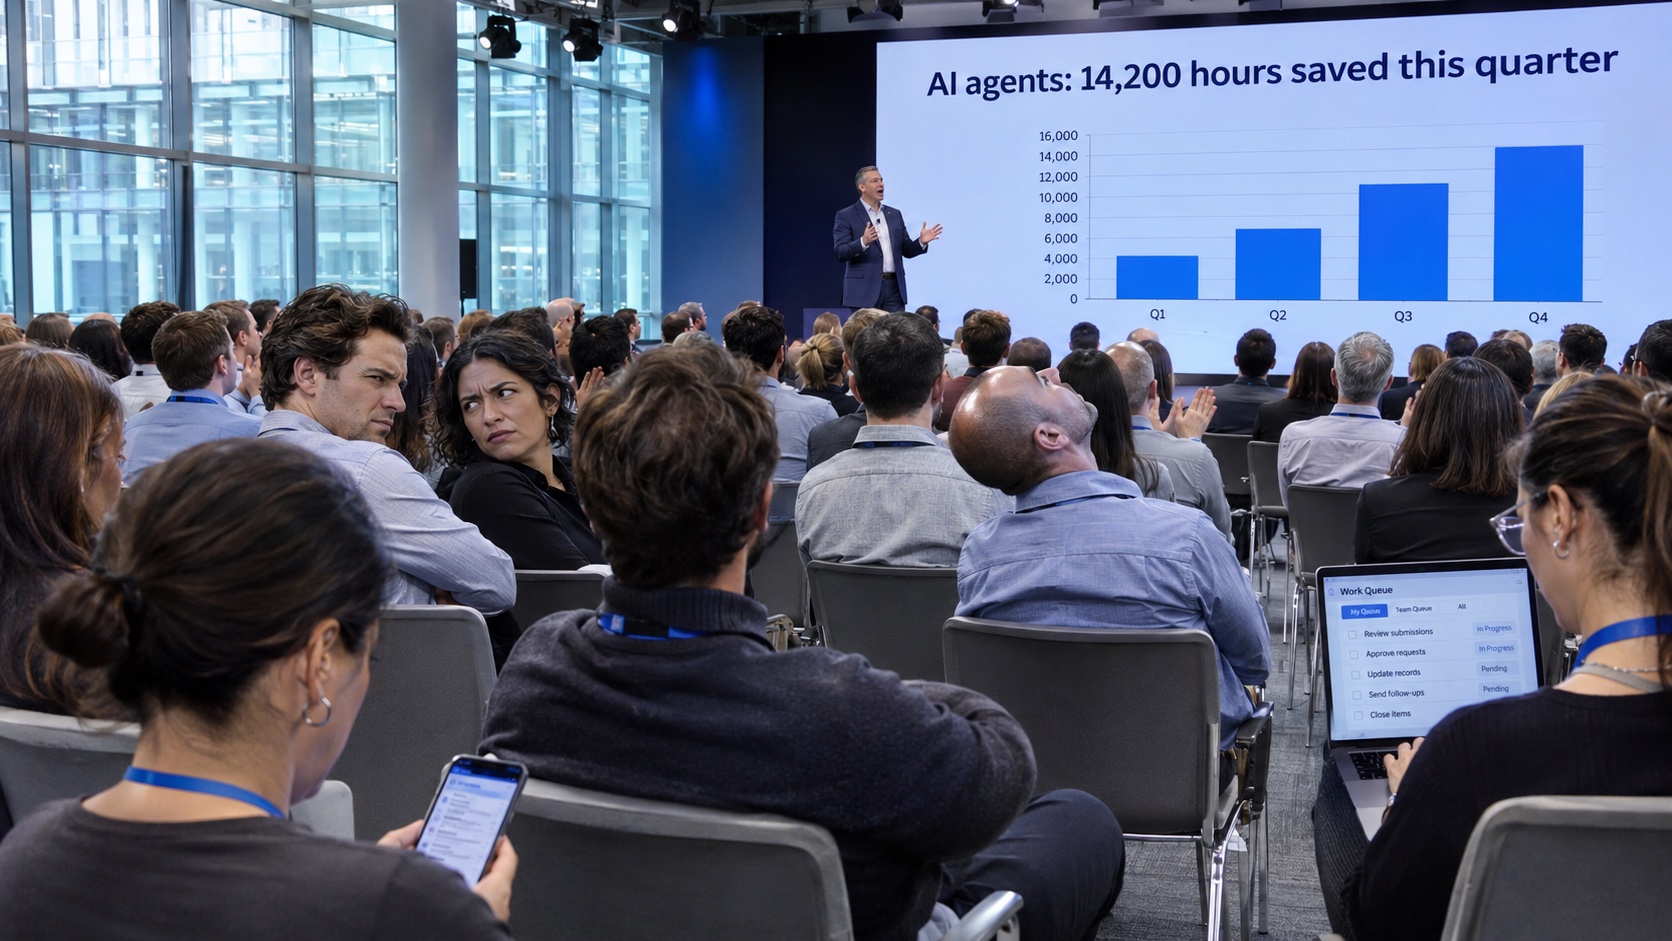
I read the agentic gap differently. Leaders and their teams have been handed two different jobs. A leader decides which work an agent takes on, changes the setup when the results disappoint, and presents the outcome. Many of the people below them approve what the agent produced. The first job is motivating. The second feels like admin, and more training won’t change how it feels.
How wide the agentic gap is
Three surveys from this year measure it. In Asana’s research, run by Censuswide with 4,502 people in the US and UK, leaders report using 4.6 agents a week and workers 2.6. Workday’s September survey of nearly 6,000 workers found that 88% of senior leaders have used agentic AI to complete a task, against 54% of individual contributors. Heavy AI use stands at 44% for senior leaders and 9% for individual contributors. Gallup has tracked it over time: frequent AI use among leaders went from 17% in 2023 to 51% in the second quarter of 2026. For individual contributors it went from 9% to 26%.
A caution before I build on these. They’re self-reported surveys, two of them come from companies that sell work software, and Asana says its leader and worker samples aren’t matched by employer. But they point the same way, and Gallup’s numbers show the distance growing.
The figure I’d look at first is a different one. Only 23% of the workers in Asana’s survey say the agents being introduced address the tasks they most need help with. Somebody chose which work the agents would take over. For more than three in four of these people, it wasn’t the work they most wanted help with.
The leader’s job: choose, look, adjust
Think about what a leader does with agents over a quarter. They pick a process to hand over. They try a setup, look at what comes back and change it. Every step is a decision with a visible result, and the next decision builds on that result.
In the Octalysis Framework this is Core Drive 3: Empowerment of Creativity & Feedback. Yu-kai Chou introduces it in Actionable Gamification with the Lego of his childhood, which gave him joy “simply because it allowed one to be creative and see immediate results”. It’s an intrinsic drive. You don’t need a reward for doing it, because trying something and seeing what happens is enjoyable by itself. He also warns that it’s “possibly the hardest to implement correctly”.
A leader gets it without anyone having to design it. Their position hands it to them.
They get two more things. The result is visible to the people who matter to them: hours saved and processes handed over go into a board update with their name on it. That’s Core Drive 2: Development & Accomplishment, the feeling of progress you can see and show. And because they shaped the setup, it’s theirs. Of Core Drive 4: Ownership & Possession, the book says that when a person feels ownership over something, “they innately want to increase and improve what they own”. So the leader keeps improving the setup, and keeps using it.
You can see the result in Gallup’s data. 21% of leaders call the effect of AI on their productivity extremely positive. Among individual contributors it’s 13%.
Ownership has a cost, though. In this year’s Wharton and GBK Collective AI adoption report, 76% of VPs and above say they trust AI output with little checking. In Workday’s survey, only 44% of employees overall say they can rely on AI output without checking it closely. Who’s right? Asana’s report sides with the workers: people who work next to agents every day are the ones who notice when an agent acts on incomplete context. “Their caution is calibrated, not uninformed.”
The worker’s job: approve what someone else set up
The Wharton and GBK report surveyed about 1,400 people at US companies with more than 1,000 employees, and asked managers how much autonomy AI gets in their department. In 35% of departments, AI drafts and a person makes every final call. In 48%, the largest group, “AI performs the work and a person reviews and approves it before anything happens”. Only 17% let AI act without a person signing off on each step.
GBK’s Brian Smith calls this the “supervised middle”, and it’s where the report finds the weakest results. Of the departments that use agents to their full capacity, 31% have transformed their workflows. Where AI only advises, it’s 25%. Where a person approves every action, it’s 16%.
The report doesn’t say who that person is. Whoever it is, look at the job. An item arrives. You approve it, or you fix it. Then the next one arrives.
Yu-kai has a test for this in the book: “If a hundred users go through your experience and all hundred take the exact same actions to achieve the Win-State, there are no meaningful choices present for the user to express their creativity.” An approval queue fails it completely. A hundred reviewers take the same two actions, all day.
And the fixing eats the benefit. A third of AI users in Workday’s survey say they lose at least half of the time AI saves them to reworking its output. A leader who delegates a task gets the time back. A reviewer often doesn’t.
Don’t most employees say they have a choice? They do. In the Wharton and GBK report, 77% of entry-level and mid-level employees agree they have meaningful choice over how and when they use AI, against 90% of managers and above. But that question is about whether I open the tool. Having a say in what the department’s agent is set up to do is something else, and there the same report shows a wider split. In departments that let AI act on its own, 66% of managers and above helped determine the strategy for their agents. Among entry-level and mid-level employees it’s 43%, and 16% say they aren’t personally involved with the agents at all. For managers that’s 4%.
Then there’s the question of who answers for mistakes. Wharton and GBK asked managers who is held responsible when an AI working on its own makes a consequential error. A governance or risk team, said 28%. The manager of the employee who deployed it, said 26%. The employee, said 25%. And 11% said nobody is clearly accountable, or they couldn’t say.
So a reviewer may answer for output they had no part in shaping, under rules that aren’t settled. In Octalysis that’s Core Drive 8: Loss & Avoidance, one of the Black Hat drives. Black Hat design creates urgency, and it has a price: people feel less in control. The less in control people feel, the more they look for a way out. An employee can’t quit a work tool. What they can do is keep quiet about it. In Workday’s survey, 41% of AI users say they’ve deliberately concealed their AI use on a work task, and only 35% of employees say their employer’s expectations for disclosure are very or extremely clear. Workday doesn’t claim a cause. Mine is that this is what pressure does to people who have no way to act on it.
Is the agentic gap a training problem?
Partly. Training is the largest gap in the Wharton and GBK data: 78% of managers and above say employees receive adequate AI training, and 56% of entry-level and mid-level employees agree. So yes, fix the training.
But training teaches a person how to work the queue. A well-trained reviewer still has the same two buttons.
We design every experience across four phases: Discovery, Onboarding, Scaffolding and the Endgame. An agent rollout normally covers the first two. There’s an announcement, a training and a first task that goes well. After that, the design doesn’t change. Month six looks like week one, and work that never changes gets stale and starts to feel like work in the bad sense. In a consumer product, this is the point where people leave. Employees can’t leave, so they do the minimum. I’ve written before about why AI adoption is a motivation design challenge and why people ignore AI agents even when the tools are good. The agentic gap is that same problem, split by rank.
How to close the agentic gap
Give the people who do the daily work parts of the leader’s job, as far as their role and the risk allow.
Start with who chooses the work. The team knows which tasks are repetitive, low in risk and easy to check. Asana’s 23% is what you get when somebody else chooses for them.
Then give reviewers a way to change how the agent behaves, and show them what the change did. Say your accounts payable team has an agent that matches supplier invoices to purchase orders, and one analyst notices that most of their corrections are partial deliveries. Can they propose that the agent stops attempting those and routes them to a person? Will they see next week what that did to the number of corrections? If so, they have a choice with a consequence, and feedback on it. If not, they have a queue. An older article of ours on the limits of control in organizations makes the same point about any job: when you can’t give people a choice of tasks, give them a choice in how the tasks get done.
Make judgment visible. A reviewer who has learned where the agent can be trusted has built a skill, and at the moment nobody can see it. Record the errors they caught and the rules they improved. That’s real achievement. A badge for prompts written is the opposite: it tells the person they wrote prompts, which they knew. Points and badges on top of a dull task don’t make it engaging, as our guide to what gamification is and what it isn’t explains. A mandate to use agents every day has the same weakness. The usage figure goes up and you learn nothing about the work.
Let the job grow with the person. Someone who has reviewed an agent’s output for six months should have something a newcomer doesn’t: the authority to change a rule, a voice in which use case comes next, a part in onboarding colleagues. That’s Scaffolding and Endgame design. Without it, your most experienced people are doing the same clicks as the person who started on Monday. It’s also what gives work its meaning when AI can do the task.
Does everyone want all this? No. Some people enjoy tuning an agent. Others want it to execute and leave them alone. We call these Player Types, and a good design gives each of them a path inside the same program.
What voluntary adoption looked like at a Procter & Gamble distributor
The project I’m about to describe had no AI agent in it. I’m using it because the problem was the same: a system the company needed its people to feed, and work around that system that nobody wanted to do.
Navo Orbico distributes Procter & Gamble brands such as Ariel and Pampers and operates in 19 countries. Its field reps sold. The CRM entries and stock checks were often neglected, and training had low completion rates. Cash bonuses were in place and no longer produced additional effort.
We built the experience over the existing CRM. Each rep became the Captain of a trading ship and chose their own strategy for growth. The choice had consequences: what a Captain decided to develop affected what the ship could carry. The team shared a Port City, and if the collective sales targets were missed, the city suffered natural disasters. A strong rep now had a reason to help a struggling colleague.
The rollout wasn’t mandatory. 99.5% of eligible employees joined. Revenue rose 28.6% against the company’s historical performance, and the published case reports a 60% improvement in KPIs for sales input activities such as accurate reporting and up-selling. Accurate reporting was exactly the kind of system work that had been neglected.
At a very different scale, we saw voluntary participation move the same way at CAIXA Econômica Federal in Brazil, which employs about 83,000 people. Participation stood at about 10%. The program we designed with the bank reached 92%, and it was voluntary.
What carries over to an agent program is the mechanism. Reps had decisions that changed their own results, and those results mattered to their colleagues. An agent program can offer both.
Measure the agentic gap in your own company
License counts and logins tell you who opened the tool. Asana’s Arnab Bose told CIO Dive that CIOs “should move away from measuring agent activity and start measuring whether work actually gets finished”. I agree, and I’d add three questions. How much time is saved once rework is counted? How much of the agent’s work is work the team picked? Do people say openly when an agent did part of a job?
Then split every answer by level. If your executives and your individual contributors give different answers, you’ve found your own agentic gap, and you know where it sits.
Where we’d start with your agent program
We’d start where we start every project, with the Strategy Dashboard. First the business metric the agent program is meant to move. Then the Desired Actions for each role. For a reviewer these could be checking with care, reporting what the agent gets wrong, proposing a rule change and saying openly when an agent did the work. Then the Player Types, because not everybody is motivated in the same way. With employees we also need to understand the culture, the hierarchy and the politics, because they decide what a person can safely admit to.
In almost all of our projects, clients discover at this stage that they were designing for the wrong thing. My guess for most agent programs is that the number on the dashboard is usage. Usage is the wrong thing.
There’s a deadline on this. Gartner predicts that more than 40% of agentic AI projects will be canceled by the end of 2027, because of “escalating costs, unclear business value or inadequate risk controls”. Rework that nobody counts adds to the first and hides the second. Our digital transformation and employee engagement work is about this: getting people to adopt a system because they want to. If your own numbers show leaders and teams far apart, Contact Us and bring them. We’ll tell you where we’d begin.
Frequently Asked Questions
What is the agentic gap?
The agentic gap is the difference in how much senior leaders and their employees use AI agents. In Asana’s September 2026 survey of 4,502 people in the US and UK, 68% of CIOs and AI leaders used three or more agents in a typical week, against 36% of AI-using office workers. Workday and Gallup report a similar split for AI use in general. The Octalysis Group’s view is that the gap comes from two different jobs: leaders direct agents, and many employees review what the agents produce.
Why do leaders use AI agents more than their teams?
Leaders choose which work an agent takes on, adjust the setup and see the result, which is Core Drive 3: Empowerment of Creativity & Feedback in the Octalysis Framework. Their results are visible and the setup feels like theirs. Many employees get an agent that was configured for a process someone else defined, and their part is to approve or correct its output. In Asana’s survey only 23% of workers said the agents being introduced address the tasks they most need help with.
Is the agentic gap a training problem?
Partly. In the 2026 Wharton and GBK Collective AI adoption report, 78% of managers and above say employees receive adequate AI training, while 56% of entry-level and mid-level employees agree. Training teaches people how to use an agent. It doesn’t give them a say in what the agent does, feedback on their own decisions or recognition for the errors they catch. Those have to be designed into the work.
Do usage mandates or badges close the agentic gap?
No. A mandate raises the usage figure without showing whether work got finished or how much time was lost to rework. A badge for prompts written or days logged in rewards activity the person already knows about. What changes behavior is letting teams choose which work the agent handles, letting reviewers change how the agent behaves and see the effect, and making their judgment visible. At Navo Orbico, a Procter & Gamble distributor, 99.5% of eligible employees joined an experience The Octalysis Group built over the existing CRM, and it wasn’t mandatory.